




Engine
Build AI products that run locally
Every model you can run, in a window that opens instantly.
It never asked for the internet in the first place.

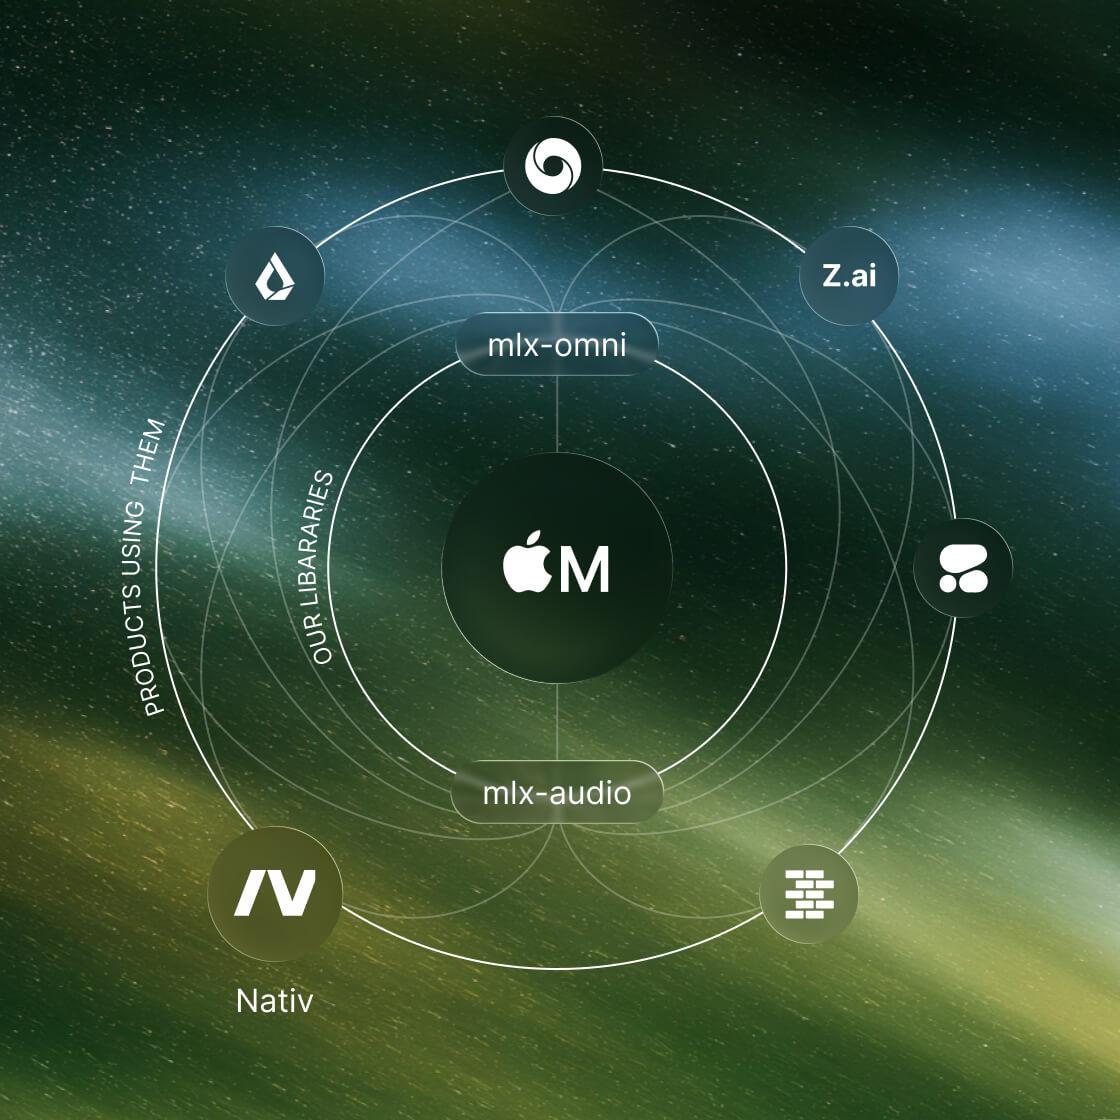
The layer between the silicon
and everything else.

MLX-VLM sits directly on the die, and exposes our libraries upward.
Both ours, and built by other
top companies out there.
Trusted by more than 7M developers
Build AI products that run locally
Build applications that can read, see, hear, speak, and create directly on personal hardware.
Our omni engine brings together our work across multimodal model support, inference, quantization, memory optimization, and device-aware performance.

VLM
Inference and fine-tuning of Vision Language Models on your Mac
 5.7k
 5.1m
- 5000+models

Audio
Speech, transcription and generation models running fully offline
- 8.1k
- 2.5m
- 5000+models
Open models from teams we trust
Access our partner models and thousands of others inside Nativ


Engine